Idempotency and Retries: Why Your System Duplicates Everything
A user submits a payment. The server processes it and returns 200, but the network drops before the response reaches the client. The client sees a timeout. It retries. The payment processes again. The user is charged twice.
This is not a bug in the payment code. The payment code did exactly what it was asked. The bug is architectural: there was no mechanism to distinguish “this is a new request” from “this is a retry of a request we already processed.”
The same bug appears in slightly different forms across every backend: a welcome email sent twice because a job fails after sending but before marking as done, a row created twice because the INSERT succeeded but the response was lost, an inventory deduction applied twice during a spike when the message queue replays an unacknowledged message.
What Idempotency Actually Means
Idempotency is the property where applying an operation multiple times produces the same result as applying it once.
GET requests are naturally idempotent - reading the same resource ten times doesn’t change anything. DELETE is usually idempotent - deleting a resource that doesn’t exist is fine. POST is not - creating a resource ten times creates ten resources.
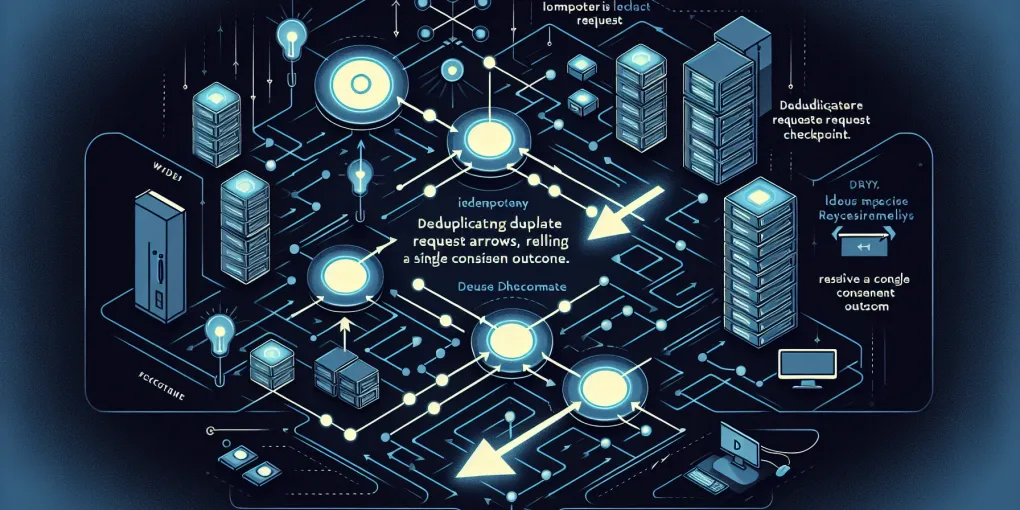
The fix is to turn your non-idempotent write operations into idempotent ones by adding a unique operation identifier. On the server, you check: have I seen this identifier before? If yes, return the stored result. If no, process and store.
# Client: generate a unique key once, retry with the same key
import uuid

def submit_payment(amount, card_token):
    idempotency_key = str(uuid.uuid4())  # generated once for this user action
    return api.post('/payments', {
        'amount': amount,
        'card_token': card_token,
    }, headers={'Idempotency-Key': idempotency_key})
# Server: check before processing, store after
def process_payment(request):
key = request.headers.get('Idempotency-Key')
if key:
cached = redis.get(f'idempotency:{key}')
if cached:
return json.loads(cached) # same request, same response
result = charge_card(request.data) # actual processing
if key:
redis.setex(f'idempotency:{key}', 86400, json.dumps(result)) # store for 24h
return resultThis is exactly what Stripe does. Every Stripe API call accepts an Idempotency-Key header. Send the same payment request with the same key twice, and Stripe returns the original response without charging again. The key is stored for 24 hours - if you retry within that window, you get the cached result.
Where This Breaks at Scale
The naive implementation above has a race condition. Two simultaneous requests with the same key can both pass the “have I seen this?” check before either one stores the result. Both get processed.
In Redis, you fix this with atomic operations:
def process_payment(request):
    key = request.headers.get('Idempotency-Key')

    if key:
        # SETNX: set only if not exists, returns 1 if set, 0 if already existed
        is_new = redis.set(f'idempotency:lock:{key}', '1', nx=True, ex=300)
        if not is_new:
            # someone else is processing or already processed this key
            cached = redis.get(f'idempotency:result:{key}')
            if cached:
                return json.loads(cached)
            # still processing - return 409 or wait
            return Response("Duplicate request in progress", status=409)

    result = charge_card(request.data)

    if key:
        redis.setex(f'idempotency:result:{key}', 86400, json.dumps(result))

    return result
In databases you can use unique constraints on the idempotency key column - the second INSERT will fail, and you can catch that and return the stored result.
The Delivery Guarantee Problem
Most distributed systems guarantee at-least-once delivery. When a message or job fails, the system retries it. This is correct - you don’t want to lose work. But it means every consumer must be idempotent.
A job queue that processes order confirmations will replay jobs if the worker crashes after processing but before acknowledging. The order confirmation email gets sent again. If you’re not deduplicating on the email address + order ID, the customer gets two emails.
The practical pattern for jobs: before doing the work, record that you’re doing it. After completing it, mark it done. On retry, check if it’s already done.
def send_order_confirmation(order_id):
    # Check if already sent
    if Email.objects.filter(order_id=order_id, type='confirmation').exists():
        return  # idempotent - already done

    # Actually send
    email_service.send(order_email(order_id))

    # Record completion
    Email.objects.create(order_id=order_id, type='confirmation')
The database’s unique constraint on (order_id, type) is the guard. If two workers process the same job simultaneously, one will get a unique constraint violation on the INSERT and bail out.
Failure Modes
Treating timeout as guaranteed failure. A timeout means “I didn’t hear back in time.” It does not mean the operation failed. The server might have processed the request and the response was lost. If your retry logic assumes a timeout equals failure, you’ll re-submit an operation that already completed.
Not scoping the idempotency key correctly. Too narrow: using a random key per attempt instead of per user action means every retry is treated as a new request. Too broad: using the same key for conceptually different operations means two distinct actions get deduplicated into one.
Making the idempotency store a single point of failure. If Redis goes down, your idempotency check is gone. You need fallback behavior - either accept the risk of duplicates during the outage, or queue requests and process them after recovery.
Forgetting about idempotency on downstream side effects. Your operation might be idempotent, but the external API it calls might not be. If your payment service calls a card processor without idempotency headers, you’ve shifted the duplicate problem downstream.
When to Apply It
Not every write operation needs explicit idempotency handling. The tradeoff is added complexity and storage overhead.
Apply idempotency to operations where duplication causes real harm:
- Payments and financial transfers
- Sending external communications (email, SMS, push notifications)
- Creating resources in external systems (provisioning infrastructure, creating accounts)
- Any message queue consumer that triggers side effects
Skip it or rely on natural idempotency for:
- Operations with unique constraints that naturally prevent duplicates (inserting a user with a unique email)
- Operations where the side effect is harmless when duplicated (logging, analytics events)
- Internal read operations
The rule: if an operation can be retried and duplication would cause a user to be harmed or a business process to fail, it needs idempotency handling. Design it in from the start - retrofitting it onto a running system is significantly harder.